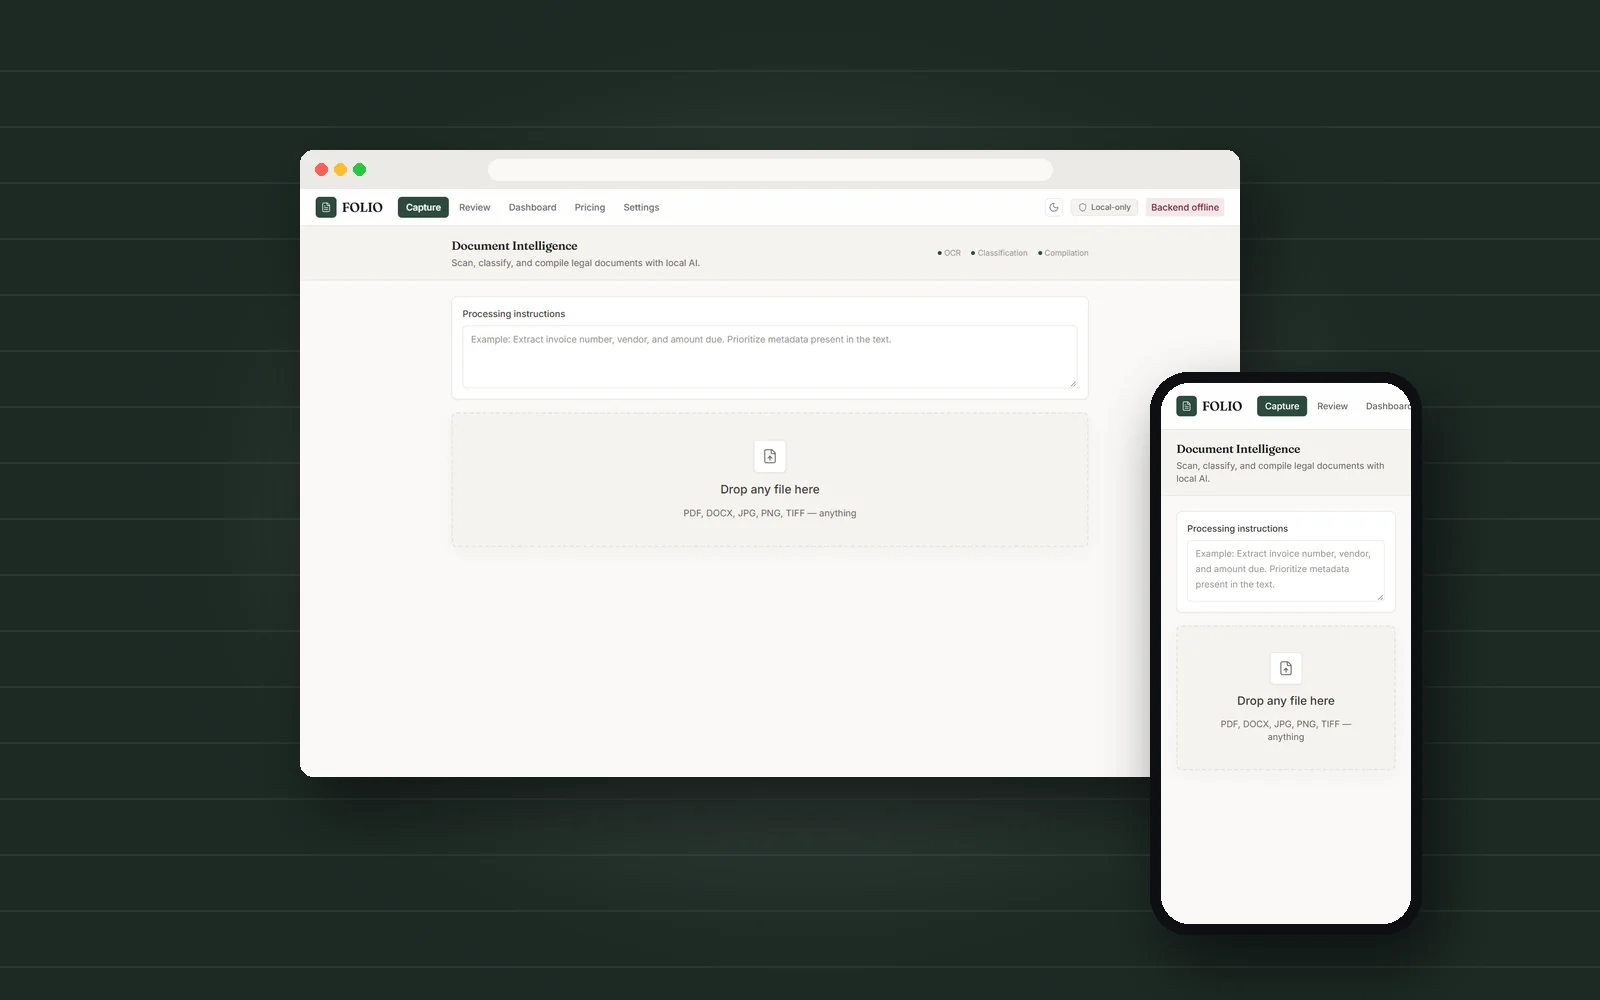
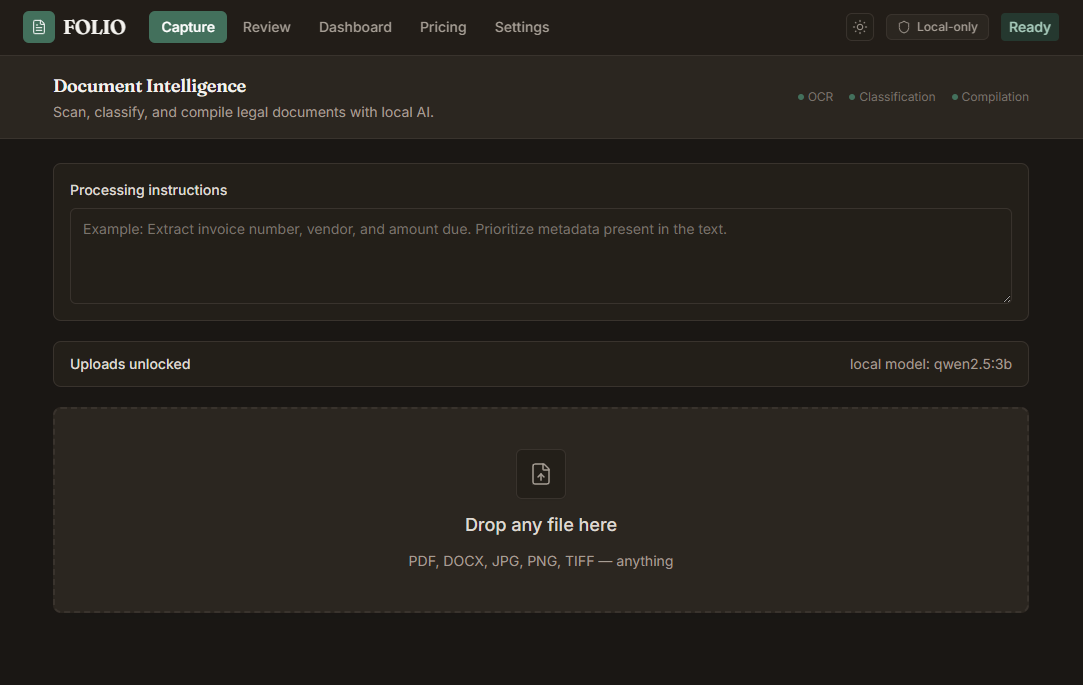
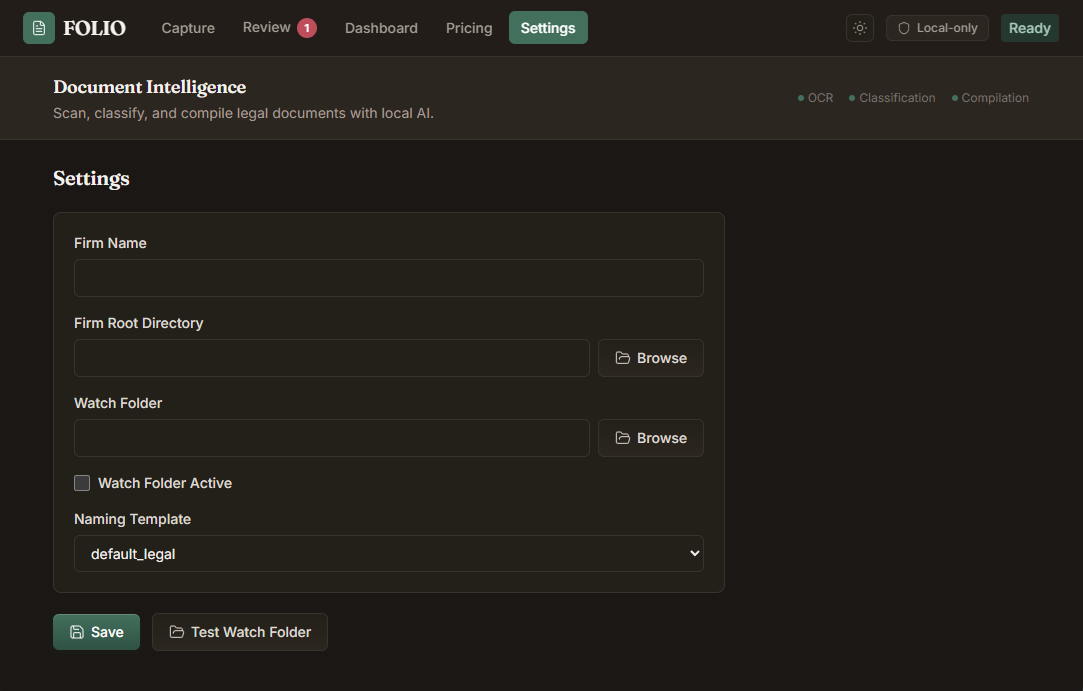
FOLIO is a document intelligence desktop app for law offices. It scans, renames, compiles, and quality-checks legal documents without sending a single file to the cloud. The whole pipeline runs on the user’s machine: Electron frontend, FastAPI Python backend, Tesseract OCR, and a local LLM for metadata extraction.
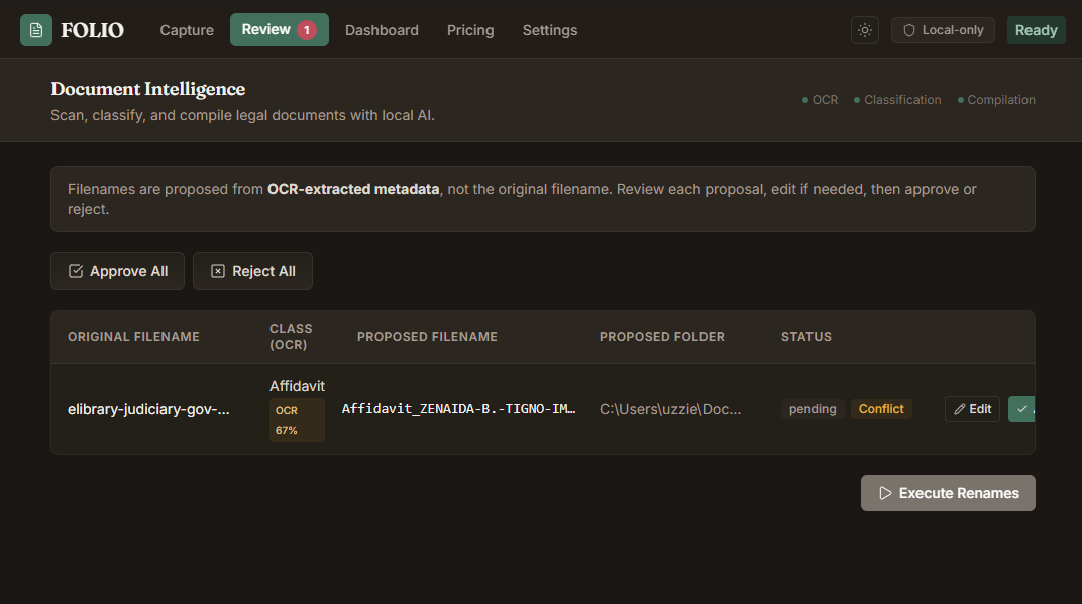
The core loop takes a folder of scanned PDFs, runs OCR to make them searchable, extracts metadata (case number, document type, date, parties) through a local language model, applies a rename template so every file follows a consistent convention, and presents a verification screen where the user approves or corrects before the files are committed.
Behind that loop are supporting pieces that make the app feel finished rather than prototyped. A watch folder that automatically ingests new files. A dashboard with session-level PDF reports. A dossier creation tool that compiles related documents into shareable bundles. An insight engine that surfaces patterns across documents — filing gaps, date clusters, repeated party names — all computed locally. A settings panel for configuring OCR language and rename templates.
I built FOLIO because the legal offices I talked to in Laguna all had the same workflow: a paralegal opens each scanned PDF, reads the first page, renames it by hand, and repeats that a hundred times per case load. The product bet is that a cheap local LLM + OCR is enough to automate the repeatable parts, and that law offices will pay a one-time desktop install fee over a monthly SaaS subscription.
Integration phase is complete — frontend, backend, and Electron shell all talk to each other with the correct data shapes. Remaining: packaging for distribution, installer, and enough field testing to know which edge cases break the OCR pipeline.